
This article records Redis’s core operations and practical experience, especially common problems and solutions in caching scenarios.
I. Basic Operations
1. Five Basic Commands
Redis’s basic interactions are very straightforward. Here is a Python (redis-py) example:
- SET key value: Write data (overwrites by default).
- GET key: Read data. If the Key does not exist, it returns
None(Python) ornil(Redis). - DEL key: Delete a Key and return the number deleted.
import redis

# 连接 Redis
r = redis.Redis(host='localhost', port=6379, db=0)

# 写入与获取
r.set("target", "127.0.0.1")
ip = r.get("target")
print(ip)  # b'127.0.0.1'

# 删除
count = r.delete("target")
print(count) # 1
2. Time to Live (TTL)
Controlling data’s lifecycle is a core capability of caching systems:
- EXPIRE key seconds: Set a Key’s “countdown” (time to live).
- TTL key (Time To Live): Check how much longer the Key will live.
import redis
import time

r = redis.Redis(host='localhost', port=6379, db=0)

r.set("test", "test") # 永不过期
r.set("target", "bx33661", ex=5) # 5秒后过期

print(r.ttl("target")) # 输出 5
time.sleep(3)
print(r.ttl("target")) # 输出 2
time.sleep(3)
print(r.ttl("target")) # 输出 -2 (已过期)
print(r.ttl("test"))   # 输出 -1 (永不过期)
Meaning of TTL return values:
> 0: Remaining lifetime in seconds.-1: The Key exists, but no expiration time has been set (it lives forever).-2: The Key does not exist at all (it has expired or was never created).
3. Batch Operations
Batch commands can reduce network overhead:
- MSET key value …: Atomically set multiple Keys.
- MGET key …: Retrieve multiple Values at once.
r.mset({
    "user:1:flag": "flag{hello}",
    "user:2:flag": "flag{world}",
    "user:3:flag": "flag{redis}"
})

flags = r.mget(["user:1:flag", "user:2:flag", "user:3:flag"])
print(flags)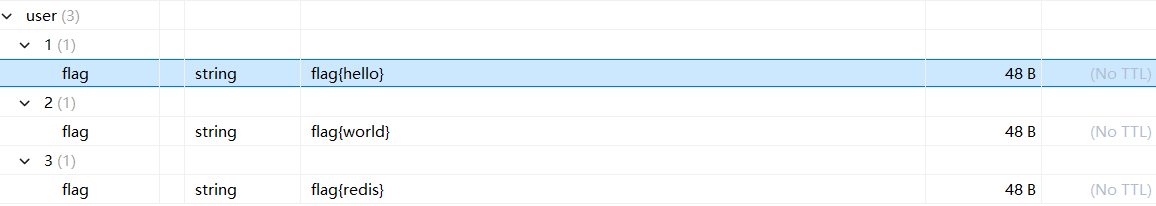
4. Pipeline
Why use a pipeline?
- Normal mode: Client sends → Server replies → Client sends… (N network round trips, or RTTs).
- Pipeline mode: Client sends N commands in a batch → Server executes them → Results are returned all at once (1 RTT).
This can provide a huge performance boost, especially for batch writes.
import redis

r = redis.Redis(host='localhost', port=6379, db=0)

# 使用 Pipeline
with r.pipeline() as pipe:
    for i in range(1000):
        pipe.set(f"task:{i}", "waiting")
        pipe.expire(f"task:{i}", 60)

    # 执行打包好的命令
    results = pipe.execute()

print(f"成功执行了 {len(results)} 个命令")
Diagram of the principle:
Python 本地内存缓冲:
┌───────────────────────────┐
│ set task:0                │
│ expire task:0             │
│ ...                       │
│ set task:999              │
└───────────────────────────┘
              │
              │ execute() (一次网络发送)
              ▼
Redis Server
II. Data Types and Use Cases
Redis is more than a KV store; it offers a rich set of data structures.
| Scenario | Recommended type | Reason |
|---|---|---|
| Token / verification code | String | Simple, with native expiration support |
| User information / object | Hash | Fields are easy to modify and use less memory than storing JSON in a String |
| Message queue / history | List | Doubly linked list, supports blocking reads (BLPOP) |
| Tags / blocklist | Set | Automatic deduplication; fast set operations (union, intersection, difference) |
| Leaderboard / delayed queue | ZSet | Automatically sorted by Score and supports range queries |
1. Hash
Suitable for storing objects, such as player attributes in a game:
# 设置玩家属性
r.hset("user:1002", mapping={
    "name": "bx",
    "age": 22,
    "score": 500
})

# 增加分数 (直接操作字段,无需取回整个对象)
r.hincrby("user:1002", "score", 100)

score = r.hget("user:1002", 'score')
print(score) # b'600'
Common commands at a glance:
| Command | Function | Typical use case |
|---|---|---|
HSET / HMGET | Set/get a field | Object storage and retrieval |
HINCRBY | Increment a field | Counters, likes |
HEXISTS | Check whether a field exists | Attribute checks |
HGETALL | Get all fields | Read a complete object (beware of large-Key risks) |
2. List
Redis List is a doubly linked list.
- Advantage: Fast O(1) insertion/deletion at the head/tail (LPUSH/RPUSH).
- Disadvantage: Slow O(N) random access to a middle element (Index).
- Use cases: Message queues, latest N updates.
3. ZSet (Sorted Set)
ZSet is Redis’s most distinctive data structure. Like Set, it deduplicates elements, but each element is associated with a Score of type Double.
Use case: CTF competition leaderboard
# 添加战队分数
r.zadd("ctf_rank", {"Team_A": 100, "Team_B": 250, "Team_C": 50})

# 获取第一名 (按分数从高到低, 0-0 即取第一个)
top1 = r.zrevrange("ctf_rank", 0, 0, withscores=True)
print(f"当前第一名: {top1}") # [('Team_B', 250.0)]

# Team_C 解出一题,加 200 分
r.zincrby("ctf_rank", 200, "Team_C")

# 查看最新全榜
print(f"最新排名: {r.zrevrange('ctf_rank', 0, -1)}")
III. Classic Cache Problems (“Three Cache Brothers”)
When designing a cache, these three extreme scenarios must be considered.
1. Cache Penetration
Symptom: A request bypasses the cache and queries the database directly, but the data is not in the database either. Consequence: The cache is completely ineffective, and under high concurrency the database can be overwhelmed by queries for nonexistent data.
Scenario simulation:
- An attacker requests
id = -1orid = 99999999(a nonexistent ID). - Redis misses → queries the DB.
- The DB also misses → nothing is written to Redis (typically, only a hit is cached).
- The process repeats, overloading the database.
Solutions:
A. Cache Null
When the DB misses, also store a special value in Redis (such as NULL or NOT_FOUND) and set a short expiration time.
# 伪代码
val = redis.get(key)
if not val:
    val = db.query(key)
    if not val:
        # 防穿透:写入空值,过期时间设短一点
        redis.set(key, "NULL", ex=60)
    else:
redis.set(key, val, ex=3600)- Disadvantage: If an attacker uses a large number of random Keys, Redis stores a lot of garbage Keys and consumes memory.
B. Bloom Filter
A Bloom filter is a highly space-efficient data structure used to determine whether “something definitely does not exist (or might exist).”
It does not store the actual data, only “fingerprints” (hash bits).
Example principle (sign-in sheet): Imagine a long strip of paper (a Bit Array), initially all zeros.
- Store
"Alice": use three hash functions to calculate positions1, 4, 7and mark those three cells (set them to 1). - Query
"Bob": calculate positions2, 5, 8. If those three cells are not all 1, we can conclude Bob is definitely not there. - Query
"Eve": calculate positions1, 4, 7. If they are all 1 (set by Alice), the filter says “Eve might be there” (a false positive in reality).
Characteristics:
- False positive rate: It may classify a nonexistent item as present (with a small probability), but it will never classify an existing item as absent. This is enough to block most malicious requests.
- Hard to delete data: Since multiple elements can share a bit, deleting one element may harm another (causing a False Negative, which is absolutely unacceptable).
2. Cache Breakdown
Symptom: A super-hot Key (such as a flash-sale product or breaking news item) suddenly expires. Consequence: At that instant, thousands of concurrent requests all discover the cache miss and hit the database at the same time, potentially bringing it down.
Solutions:
- Mutex lock: When a cache miss is detected, not every thread queries the database. Threads first compete for a lock. The winner queries the database and updates the cache; the others wait.
- Logical expiration: Do not set a Redis expiration on the data itself; instead, include a logical expiration timestamp in the Value. When a query detects logical expiration, it starts a background thread to refresh the data, while the current request returns the old value.
3. Cache Avalanche
Symptom: A large number of Keys expire at the same time, or the Redis service goes down. Consequence: The entire cache layer fails, sending all traffic crashing into the database like an avalanche.
Solutions:
- Random expiration times: Add a random value when setting expiration (for example
1小时 + random(1-5分钟)), spreading out expiration times. - High-availability architecture: Use Redis Sentinel or Cluster mode to prevent a single point of failure.
- Rate limiting and degradation: When the database cannot handle the load, enable rate-limit protection or return default degraded data directly.